The Open Lakehouse Built on Your Laptop
Step-by-step local architecture lab using Docker, RustFS or Ceph, Apache Iceberg, and Dremio. No cloud account required.

Alex Merced
Head of DevRel @ Dremio
Revision notice
Updated October 12, 2026
MinIO removed its minio/minio and minio/mc images from Docker Hub on September 11, 2026, which broke the lab’s original compose file. The lab now provides two replacement object stores, RustFS and Ceph, each with its own compose file. All Dremio steps and SQL are unchanged, since they only depend on the S3 API. The update also fixes two errors: a time-travel example that used a date before the table existed, and an inaccurate description of the file layout. Both setups were tested with Dremio 26.0.5.
$100
$100 Reward Opportunity
Earn a $100 Gift Card for Completing the Exercise
Complete the 4 lab parts and take screenshots of your terminal commands and query results at each milestone (each part prompts you for what to capture). Submit them to the #lakehouse-lab channel in the Dremio Developer Community Slack, or email [email protected] with the subject “Laptop Lakehouse Lab Verification”, to claim the $100 gift card.
Part 1The Open Lakehouse Architecture Explained
12 min read
Screenshot checkpoint: Review and save your notes on how the five layers (Parquet, Iceberg, Polaris, Arrow, Ossie) cooperate in one query as you prepare to start the hands-on lab.
Most people learn the open lakehouse backwards. They read five vendor pages, collect a stack of Apache project names, and still cannot answer a basic question: when I run a query, what does each piece actually do?
That gap is fixable in about an hour. The five projects that define the open lakehouse each own one layer of the problem, and once you see the layers separately, the architecture stops being a diagram and becomes obvious. Apache Parquet stores bytes on disk. Apache Iceberg turns a pile of those files into a table. Apache Polaris keeps track of which tables exist and who can touch them. Apache Arrow moves the data through memory and across the wire. Apache Ossie describes what the columns mean in business terms.
The second half of this article is a lab. You will run two containers on your laptop, one for object storage and one for a query engine, wire them together, and write a real Apache Iceberg table into an S3-compatible bucket. Then you will look at the files that landed and see the format layers with your own eyes. No cloud account, no credit card, no Spark cluster.
I work at Dremio, and Dremio is the query engine in the lab. I picked it because it runs in a single container and needs no external metastore, which keeps the exercise short. The concepts transfer to any engine.
1. Why the Lakehouse Split Into Layers at All
For thirty years a database was one product. Storage format, table metadata, catalog, query planner, and execution engine all shipped together and none of them were separable. That design has real advantages. The engine knows exactly how the bytes are laid out and can optimize against its own assumptions.
The cost shows up when you have more than one workload. Your BI tool wants SQL. Your data scientists want Python. Your machine learning pipeline wants to read raw files. Each of those tools has its own preferred engine, and a closed warehouse gives you exactly one door in, priced per query.
Teams solved this in the 2010s by dumping files into object storage and pointing many engines at the same directory. That worked for read-only analytics and fell apart everywhere else. Two writers touching the same directory produced corrupt results. A partially written job left half a dataset visible to readers. Renaming a column meant rewriting everything. There was no such thing as a transaction.
The lakehouse is the answer to that failure. Keep the cheap shared storage, then add back the guarantees a database gave you, defined as open specifications instead of product internals. Each guarantee lives in its own layer, and each layer has a written spec that anyone can implement.
The result is a stack you assemble rather than buy. Storage from one vendor, catalog from another, three engines reading the same tables at once, and no rewrite when you swap any single piece. That portability is the entire point, and it only works because the layers stay honest about their boundaries.
2. Apache Parquet: The File Layer
Parquet is a columnar file format. It is the oldest project in this group, donated to the Apache Software Foundation in 2015, and it is the default storage format for nearly every analytics system built since.
A CSV file stores data by row. All of order 1, then all of order 2. To sum one column across ten million rows, you read all ten million rows in full. Parquet flips that. It groups rows into chunks called row groups, and inside each row group it stores each column contiguously. To sum one column, you read that column and skip the rest.
Three properties fall out of that layout, and all three matter more than people expect:
- Compression gets far better: A column holds one data type with repeated values, so run-length encoding and dictionary encoding do real work. A column of country codes with 200 distinct values compresses to almost nothing. Mixed row data never compresses that well.
- Column pruning saves I/O: A query touching 3 columns out of 80 reads about 4 percent of the file. On object storage, where you pay per byte transferred and latency dominates, that is the difference between a two-second query and a two-minute one.
- Predicate pushdown skips whole chunks: Each row group carries footer statistics with the minimum and maximum value per column. A query filtering on
order_date > '2026-01-01'reads the footer, sees that a row group tops out at 2025-06-30, and skips it without decompressing a single page.
What Parquet does not give you is a table. A Parquet file knows its own schema and its own statistics. It has no idea that 4,000 sibling files in the same prefix belong to the same logical dataset, no notion of a transaction, and no way to express that three of those files were replaced by one this morning. That is the next layer's job.
3. Apache Iceberg: The Table Layer
Iceberg is a specification for describing a table as a set of files, plus enough metadata to make changes to that set atomic. It came out of Netflix, was donated to the ASF in 2018, and graduated to a top-level project in 2020. The current stable Java library line is 1.11, released in mid-2026, and it implements format version 3 of the specification.
The distinction between library version and format version confuses people constantly. The library version, 1.11, is a piece of software. The format version, 3, is the on-disk contract that any implementation in any language has to honor. When a vendor says they support Iceberg, ask which format version and which operations.
Here is the structure, from the bottom up:
- Data files: Parquet files holding the rows. Iceberg supports ORC and Avro too, and Parquet is what nearly everyone uses.
- Manifest files: An Avro file listing data files, each with its partition values, row count, and per-column min/max statistics. One manifest describes a batch of data files.
- Manifest lists: An Avro file listing the manifests that make up one snapshot, with partition range summaries for each.
- Metadata files: A JSON file holding the table schema, the partition specification, the sort order, table properties, and the full history of snapshots. Every write produces a new metadata file.
- The catalog pointer: One tiny piece of mutable state: which metadata file is current. Everything below it is immutable.
That last point carries all the weight. Because every file below the pointer never changes, a writer builds a complete new version of the table off to the side, then swaps the pointer in one atomic operation. Readers that started before the swap keep reading the old snapshot and see a consistent view. Readers that start after see the new one. Nobody ever sees half a commit.
Once you have immutable snapshots, several features come free rather than being bolted on:
- Time travel is just reading an older metadata file.
SELECT * FROM sales AT SNAPSHOT '8234...'resolves a snapshot ID and reads the file list from that point in history. - Rollback is repointing the catalog at a previous metadata file. A bad load at 3 a.m. gets undone in one statement instead of a restore from backup.
- Schema evolution works because Iceberg tracks columns by a unique integer ID, not by name or position. Rename a column and the ID stays the same, so old data files still resolve correctly. Add a column and old files report null for it. Drop a column and nothing gets rewritten.
- Hidden partitioning removes the worst footgun of the Hive era. In Hive, a table partitioned by day required every query to filter on the partition column by name, and a query filtering on the raw timestamp scanned everything. Iceberg records the partition as a transform of a source column, so a filter on
order_tsautomatically prunes partitions defined asday(order_ts). Users stop needing to know the physical layout.
One thing Iceberg deliberately leaves out is where that catalog pointer lives. The specification defines the file formats and the commit protocol, then hands the pointer problem to a pluggable catalog. Implementations include the Hive Metastore, AWS Glue, a plain filesystem-based catalog, and the REST catalog protocol that Polaris implements.
Format version 3 added deletion vectors, which replace v2 position delete files with compact bitmaps. Updating a handful of rows no longer forces a rewrite of the data files that contain them, and merge-on-read queries get faster. V3 also added a variant type for semi-structured JSON and mandatory row lineage tracking.
4. Apache Polaris: The Catalog Layer
The catalog is the smallest component in the stack and the one that decides how open your architecture really is.
An Iceberg catalog does one job well: map a table name to the location of its current metadata file, and swap that pointer atomically when a writer commits. Add a second job on top and you have a governance boundary, because every engine has to ask the catalog where a table lives before it can read the table.
Apache Polaris is an open source implementation of the Iceberg REST Catalog specification. It was co-created by Dremio and Snowflake, donated to the Apache Software Foundation, and graduated to a top-level project on February 18, 2026.
Two things make the REST catalog spec matter more than older catalog options:
- It standardizes the protocol instead of the implementation: Older catalog choices bound you to a client library. The REST spec turns catalog access into HTTP with a documented JSON contract, so an engine written in Rust or Python talks to the same catalog as one written in Java without shipping proprietary clients.
- It moves commit logic to the server: In the older model, the client library built the new metadata and performed the atomic swap. With REST, the client sends the requested change and the server performs the commit atomically. One implementation of the hard part, shared by everyone.
Polaris adds credential vending on top of that. Instead of giving each engine long-lived storage keys, the catalog holds the storage credentials. An engine asks for a table, the catalog checks the caller's permissions, and returns a short-lived, narrowly scoped storage credential valid for that table's location only. Access control lives in one place instead of being duplicated across every engine's configuration and bucket policies.
The lab below does not use Polaris because running a separate catalog service, a database for state, object storage, and an engine is four containers and extra configuration. Dremio ships with an internal Iceberg catalog that handles the pointer for us, and the file layout you inspect at the end is identical either way.
5. Apache Arrow: The In-Memory Layer
Parquet is how data rests. Arrow is how data moves.
Apache Arrow defines a standard columnar layout for data in memory, plus a serialization format for sending that layout over a network without changing it. It was co-created by Jacques Nadeau, now the CTO at Dremio, and it has become the connective tissue between analytics tools.
Arrow removes serialization tax by making the in-memory layout and the wire layout the same thing. A record batch on the server is copied to the socket, and the client points at the received bytes as a valid Arrow buffer with zero parsing overhead.
The layout is also built for modern CPUs. Values in a column sit in a contiguous buffer with a separate validity bitmap for nulls, allowing query engines to process 8 or 16 values per instruction using SIMD registers. Two adjacent protocols include Arrow Flight (for moving Arrow record batches between processes) and Arrow Flight SQL (database-style interface on top, exposed by Dremio on port 32010).
6. Apache Ossie: The Semantic Layer
The newest project in this group solves the problem that survives after all the technical layers work perfectly: definition drift.
Apache Ossie is an open specification for semantic layers and ontologies. It entered the Apache Incubator on June 22, 2026. Ossie defines a vendor-neutral YAML format for expressing metrics, dimensions, relationships, and broader business concepts. A BI platform, a query engine, or an AI agent reads the same definition file and computes the same number.
Giving AI agents a machine-readable, governed definition of what a metric means is the difference between an agent that helps and one that generates plausible nonsense at scale. Contributors include Snowflake, Salesforce, Databricks, dbt Labs, RelationalAI, GoodData, and Honeydew.
7. How the Five Layers Cooperate in One Query
Walk a single query through the stack and the division of labor becomes concrete:
SELECT region, SUM(amount)
FROM sales
WHERE order_date >= DATE '2026-01-01'
GROUP BY region;
- The engine parses the SQL and asks the catalog for the table named
sales. The catalog checks permissions and returns the location of the current metadata file. - The engine reads the Iceberg metadata file, follows it to the manifest list for the current snapshot, and reads the manifests. It drops every data file whose
order_datemaximum falls before 2026-01-01, pruning thousands of files without reading raw data. - For each surviving Parquet file, the engine reads the footer, drops row groups failing the filter, and requests byte ranges covering only the referenced columns.
- Those bytes get decoded into Arrow buffers in memory. Aggregation runs vectorized with SIMD over those buffers.
- The final result travels to the client as Arrow record batches over Flight SQL, with no serialization step.
- If using Ossie, the analyst never wrote that SQL manually: a governed metric model generated consistent query syntax.
| Layer | Project | Lives Where | Answers the question |
|---|---|---|---|
| File | Apache Parquet | On disk, in object storage | How are these bytes encoded and compressed? |
| Table | Apache Iceberg | Metadata files next to the data | Which files make up this table right now? |
| Catalog | Apache Polaris | A service with its own database | Which tables exist, and who is allowed in? |
| Memory and transport | Apache Arrow | RAM and the network socket | How is the data laid out while being processed? |
| Meaning | Apache Ossie | Version-controlled YAML | What does this metric mean? |
Five specifications, five jobs, zero overlap. Now let us stand up this architecture on your laptop.
Part 2Preparing Your Environment & Starting the Stack
6 min read
Screenshot checkpoint: Take a screenshot of your terminal showing successful container startup (docker compose up -d or docker compose logs) and the Dremio first-user setup page at http://localhost:9047.
1. The Lab: What You Are Building
Two containers, plus a short-lived helper for one of the storage options:
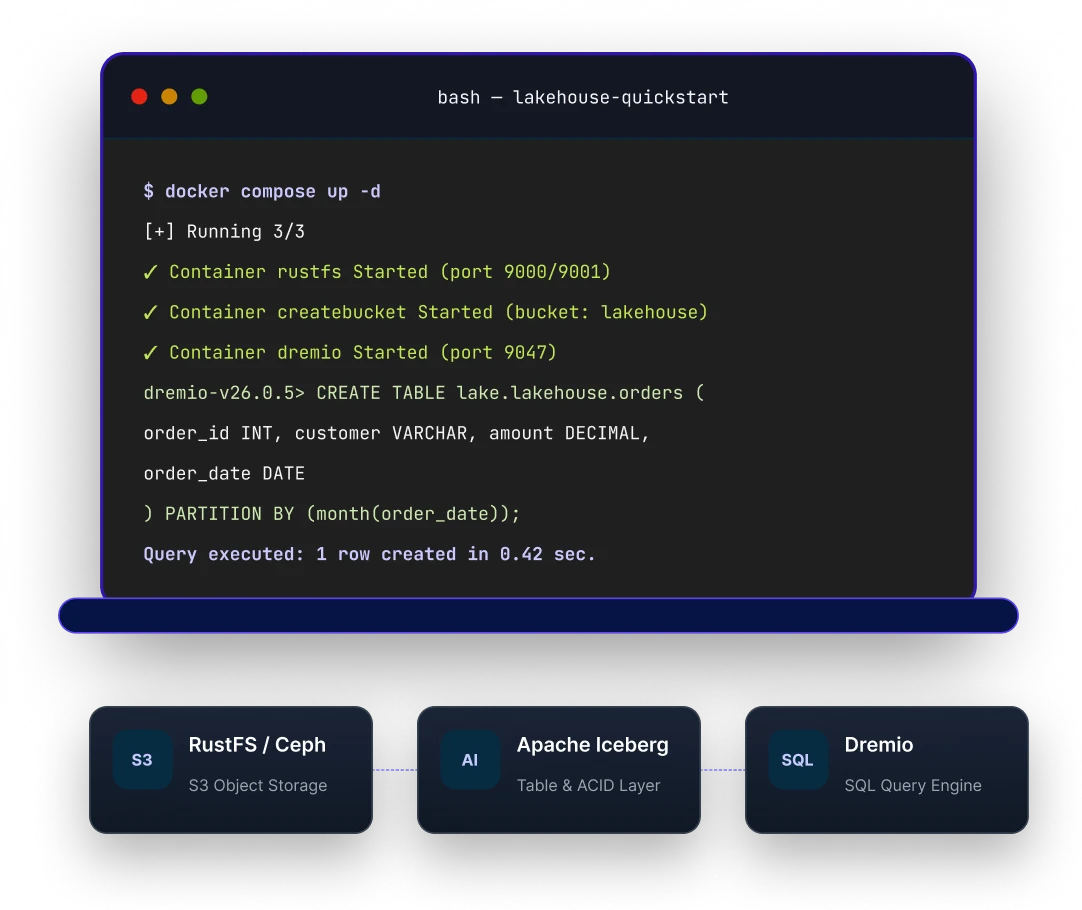
- An S3-compatible object store holds your data lake. You pick one of two: RustFS (a single high-performance Rust binary with a browser UI) or Ceph RADOS Gateway (the production-grade S3 front end used in enterprise clouds). Both speak the standard S3 API.
- Dremio provides the SQL engine, the Iceberg write path, and the web console. Dremio Community Edition runs as a single container with an embedded coordinator, executor, and ZooKeeper.
Why not MinIO? Earlier versions of this lab used MinIO, but MinIO deleted its minio/minio and minio/mc images from Docker Hub on September 11, 2026. This lab now uses modern S3-compatible alternatives (RustFS or Ceph), keeping the S3 API and every Dremio query identical.
System Requirements: Docker Desktop, roughly 8 GB of RAM allocated to Docker, and about 10 GB of free disk space.
2. Choosing Between RustFS and Ceph
RustFS is the recommended faster path: it starts in seconds, uses ~150 MB of memory, includes a web file browser on port 9001, and supports Intel and Apple Silicon natively. Ceph runs a full Ceph monitor, manager, OSD, and RGW daemon in one container. It is heavier and runs under x86 emulation on ARM Macs.
| Feature | RustFS (Recommended) | Ceph RGW (Demo Image) |
|---|---|---|
| Image | rustfs/rustfs:1.0.1 | quay.io/ceph/demo:latest-squid |
| S3 endpoint for Dremio | rustfs:9000 | ceph:8080 |
| Web file browser | Yes, port 9001 | No (command line only) |
| Bucket creation | Helper container | Built into the image |
| Startup time | A few seconds | About a minute |
| Apple Silicon | Native | Emulated |
3. Compose File A: RustFS (Recommended)
Create a new directory, save this content as docker-compose.yml:
services:
  rustfs:
    image: rustfs/rustfs:1.0.1
    container_name: rustfs
    ports:
      - "9000:9000"
      - "9001:9001"
    environment:
      RUSTFS_ACCESS_KEY: admin
      RUSTFS_SECRET_KEY: password
      RUSTFS_ADDRESS: ":9000"
      RUSTFS_CONSOLE_ADDRESS: ":9001"
      RUSTFS_CONSOLE_ENABLE: "true"
    volumes:
      - rustfs-data:/data
    networks:
      - lakehouse

  createbucket:
    image: amazon/aws-cli:2.37.12
    container_name: createbucket
    depends_on:
      - rustfs
    environment:
      AWS_ACCESS_KEY_ID: admin
      AWS_SECRET_ACCESS_KEY: password
      AWS_DEFAULT_REGION: us-east-1
    entrypoint: >
      /bin/sh -c "
      aws configure set default.s3.addressing_style path;
      until aws --endpoint-url http://rustfs:9000 s3 ls; do sleep 2; done;
      aws --endpoint-url http://rustfs:9000 s3 mb s3://lakehouse || true;
      aws --endpoint-url http://rustfs:9000 s3 ls;
      "
    networks:
      - lakehouse

  dremio:
    image: dremio/dremio-oss:26.0.5
    container_name: dremio
    ports:
      - "9047:9047"
      - "31010:31010"
      - "32010:32010"
      - "45678:45678"
    environment:
      DREMIO_JAVA_SERVER_EXTRA_OPTS: -Dpaths.dist=file:///opt/dremio/data/dist
    volumes:
      - dremio-data:/opt/dremio/data
    depends_on:
      - rustfs
    networks:
      - lakehouse

volumes:
  rustfs-data:
  dremio-data:

networks:
  lakehouse:
Key details: Pinned tag rustfs/rustfs:1.0.1; S3 API on port 9000, console on port 9001; non-root user volume isolation; createbucket helper with AWS CLI path-style addressing; and Dremio 26.0.5 on port 9047 (web) and 32010 (Flight SQL).
4. Compose File B: Ceph (Alternative)
If you prefer Ceph, save this as docker-compose.yml instead:
services:
  ceph:
    image: quay.io/ceph/demo:latest-squid
    platform: linux/amd64
    container_name: ceph
    hostname: ceph
    ports:
      - "8080:8080"
    environment:
      MON_IP: 127.0.0.1
      CEPH_PUBLIC_NETWORK: 0.0.0.0/0
      DEMO_DAEMONS: osd,rgw
      CEPH_DEMO_UID: demo
      CEPH_DEMO_ACCESS_KEY: admin
      CEPH_DEMO_SECRET_KEY: password
      CEPH_DEMO_BUCKET: lakehouse
    volumes:
      - ceph-etc:/etc/ceph
      - ceph-data:/var/lib/ceph
    networks:
      - lakehouse

  dremio:
    image: dremio/dremio-oss:26.0.5
    container_name: dremio
    ports:
      - "9047:9047"
      - "31010:31010"
      - "32010:32010"
      - "45678:45678"
    environment:
      DREMIO_JAVA_SERVER_EXTRA_OPTS: -Dpaths.dist=file:///opt/dremio/data/dist
    volumes:
      - dremio-data:/opt/dremio/data
    depends_on:
      - ceph
    networks:
      - lakehouse

volumes:
  ceph-etc:
  ceph-data:
  dremio-data:

networks:
  lakehouse:
Key Ceph configuration: hostname: ceph ensures the RGW daemon matches the host Dremio connects to. Without it, RGW parses the host header as a bucket name and throws NoSuchBucket.
5. Starting the Stack
Launch your environment:
docker compose up -d
docker compose logs -f dremio
Dremio takes 60 to 120 seconds to boot on a laptop. When you see the log line indicating the Dremio Daemon started, navigate to http://localhost:9047 to complete the first-time admin registration form.
Confirm bucket creation: run docker compose logs createbucket (for RustFS) and verify lakehouse appears in the output. For Ceph, run docker compose logs ceph and look for SUCCESS.
Part 3Hands-On Lab: Writing, Querying & Inspecting Iceberg Tables
10 min read
Screenshot checkpoint: Take a screenshot of the Dremio SQL Runner showing the result of your snapshot query (table_snapshot) or time travel query, AND a screenshot of your storage file tree (RustFS web console at http://localhost:9001 or AWS CLI listing).
1. Adding the Object Store as a Dremio Source
In the Dremio console, click Add Source (bottom-left) and select Amazon S3. Both RustFS and Ceph implement the standard S3 API, so Dremio's S3 connector communicates with either seamlessly.
Step A: General Tab
- Name:
lake(naming the sourcelakekeeps all subsequent SQL identical regardless of which store you selected) - Authentication: AWS Access Key
- AWS Access Key:
admin - AWS Access Secret:
password - Encrypt connection: Uncheck (local containers run plain HTTP)
Step B: Advanced Options
- Enable compatibility mode: Check
- Default CTAS Format:
ICEBERG(Essential: prevents default Parquet-only writes) - Root Path:
/
| Property Name | RustFS (Recommended) | Ceph RGW (Demo Image) |
|---|---|---|
fs.s3a.endpoint | rustfs:9000 | ceph:8080 |
fs.s3a.path.style.access | true | true |
dremio.s3.compat | true | true |
Click Save. The source will appear in the left sidebar; expanding it displays the lakehouse bucket.
2. Writing and Reading Iceberg Tables
Open the SQL Runner in Dremio and execute:
CREATE TABLE lake.lakehouse.orders (
  order_id     INT,
  customer     VARCHAR,
  region       VARCHAR,
  amount       DOUBLE,
  order_date   DATE
) PARTITION BY (month(order_date));
Insert sample records into your partitioned table:
INSERT INTO lake.lakehouse.orders VALUES
  (1, 'Acme Corp',    'East',  1200.50, DATE '2026-01-15'),
  (2, 'Globex',       'West',   890.00, DATE '2026-01-22'),
  (3, 'Initech',      'East',  2340.75, DATE '2026-02-03'),
  (4, 'Umbrella Ltd', 'North', 1500.00, DATE '2026-02-18'),
  (5, 'Soylent Inc',  'West',   675.25, DATE '2026-03-07');
Query the table with an aggregation:
SELECT region, SUM(amount) AS total, COUNT(*) AS orders
FROM lake.lakehouse.orders
GROUP BY region
ORDER BY total DESC;
Now inspect the metadata history using Iceberg table functions:
SELECT * FROM TABLE(table_snapshot('lake.lakehouse.orders'));Perform mutations to see new snapshots committed atomically:
UPDATE lake.lakehouse.orders
SET amount = 1300.00
WHERE order_id = 1;

DELETE FROM lake.lakehouse.orders
WHERE region = 'North';

INSERT INTO lake.lakehouse.orders VALUES
  (6, 'Hooli', 'East', 4100.00, DATE '2026-03-22');
Re-query snapshots, copy a snapshot ID from after the first insert, and time travel back to it:
SELECT * FROM lake.lakehouse.orders
AT SNAPSHOT '<paste_snapshot_id_here>'
ORDER BY order_id;
You can also time travel by timestamp:
SELECT COUNT(*) FROM lake.lakehouse.orders
AT TIMESTAMP '<paste_committed_at_here>';
Test schema evolution and compaction:
ALTER TABLE lake.lakehouse.orders ADD COLUMNS (sales_rep VARCHAR);

OPTIMIZE TABLE lake.lakehouse.orders;
3. Looking at the Files You Just Created
On RustFS, visit http://localhost:9001 (login: admin / password) and navigate into lakehouse/orders/.
metadata/contains versioned metadata JSON (v1.metadata.json,v2.metadata.json, etc.),version-hint.text, manifest lists (snap-*.avro), and partition stats.- Job folders contain raw Parquet files partitioned into directory suffixes like
672(Jan 2026),673(Feb 2026), and674(Mar 2026).
Command Line Inspection: Inspect the full S3 object hierarchy from your terminal via AWS CLI:
docker run --rm --network <your_project>_lakehouse \
  -e AWS_ACCESS_KEY_ID=admin \
  -e AWS_SECRET_ACCESS_KEY=password \
  -e AWS_DEFAULT_REGION=us-east-1 \
  --entrypoint /bin/sh amazon/aws-cli:2.37.12 -c \
  "aws configure set default.s3.addressing_style path && \
   aws --endpoint-url http://rustfs:9000 s3 ls --recursive s3://lakehouse/orders/"
Notice that mutations did not rewrite existing files; they committed new snapshot metadata pointing to new immutable files.
Part 4Troubleshooting, Extensions & Claiming Your $100 Reward
6 min read
Screenshot checkpoint: Take a final screenshot of this completion section and assemble your screenshots from each part to submit for your $100 gift card!
1. What Breaks, and How to Recognize It
Why not MinIO? Earlier versions of this lab used MinIO, but MinIO deleted its minio/minio and minio/mc images from Docker Hub on September 11, 2026. This lab now uses modern S3-compatible alternatives (RustFS or Ceph), keeping the S3 API and every Dremio query identical.
System Requirements: Docker Desktop, roughly 8 GB of RAM allocated to Docker, and about 10 GB of free disk space.
Common troubleshooting scenarios encountered when running local lakehouse environments:
pull access denied for minio/minio: Running an obsolete compose file; use the RustFS or Ceph compose files from Part 2.- Source saves but displays no buckets: Verify Root Path is
/and bucket was created (checkdocker compose logs createbucket). - Connection refused on port 9000 or 8080: Ensure endpoint uses the container service name (
rustfs:9000orceph:8080), notlocalhost. NoSuchBucketon Ceph: Container hostname mismatch. Ensurehostname: cephis present in compose file.- Ceph fails to start with file conflict: Volume state mismatch; run
docker compose down, deleteceph-etcandceph-datavolumes, and re-launch. - RustFS permission denied on data volume: If using a host bind mount, run
chown -R 10001:10001on the target directory. - SSL/Handshake failure: Encrypt connection was left checked; uncheck it because local containers communicate over HTTP.
- Signature mismatch: Ensure path-style access is enabled (
fs.s3a.path.style.access = true) and keys match exactly. - Table created without metadata: Default CTAS format was not set to
ICEBERGin Dremio Advanced Options. - Time travel out-of-range error: The timestamp requested precedes the table's first commit snapshot.
- Dremio UI unreachable on 9047: Docker daemon ran out of memory; increase Docker memory limit to 8 GB.
- Stale metadata from external writes: Run
ALTER TABLE lake.lakehouse.orders REFRESH METADATA. - Data deleted after restarting stack: Avoid using
docker compose down -vwhich deletes named volumes.
2. Where to Take This Next
To expand your local lakehouse into a production-like multi-engine architecture:
- Add Apache Polaris: Run a standalone Polaris REST catalog container backed by PostgreSQL, point Dremio to Polaris, and enable multi-engine credential vending.
- Add Apache Spark: Start a Spark container with the Iceberg runtime, point it at the same Polaris catalog, and test writing in Spark and reading instantly in Dremio.
- PyIceberg & DuckDB: Query Iceberg metadata directly from Python data science notebooks without a full query engine.
- Arrow Flight SQL Client: Connect Python or Go via port 32010 to stream Arrow record batches at wire speed.
3. Conclusion & Deliberate Breakage
The open lakehouse is not a vendor product: it is a set of open specifications that decouple storage (Parquet), table transactions (Iceberg), catalog governance (Polaris), vectorized in-memory compute (Arrow), and semantic business metrics (Ossie).
Break your compose file deliberately: change the endpoint, toggle compatibility mode, or test CTAS behavior. An hour of deliberate experimentation teaches more than weeks of theoretical architecture diagrams.
Keep Going: Open Lakehouse Resources & Community
Continue your open lakehouse journey with these official Dremio developer resources:
Iceberg & Polaris Guides
Download complimentary full-length architectural reference books for Apache Iceberg and Apache Polaris.
Explore Free Books Live EventsJoin an Open Source Event
Connect with maintainers and practitioners at live meetups, webinars, and open lakehouse hackathons.
View Event Calendar Weekly NewsletterOpen Lakehouse & AI
Get weekly architecture breakdowns, engine benchmarks, and Apache Iceberg tips delivered to your inbox.
Subscribe to NewsletterFinal Step
Claim Your $100 Reward
Congratulations on completing the hands-on lab! To claim your $100 gift card, assemble your screenshots from the milestone checkpoints and submit them through the verification form.